Liquid AI LFM3 Breaks Edge AI Limits: 1.7B Tri-Hybrid Architecture Outperforms 9B Models
Introduction
On October 27, 2026, Liquid AI officially released the LFM3 family of open-weight multimodal models. The flagship 1.7B-parameter model outperformed the Qwen3.5-9B — a model five times its size — on multiple agentic task benchmarks, sending shockwaves through the AI industry. This breakthrough redefines the performance boundaries of edge AI and opens new possibilities for enterprises across the Asia-Pacific region to deploy high-performance AI locally.
The Tri-Hybrid Architecture: LFM3's Technical Core
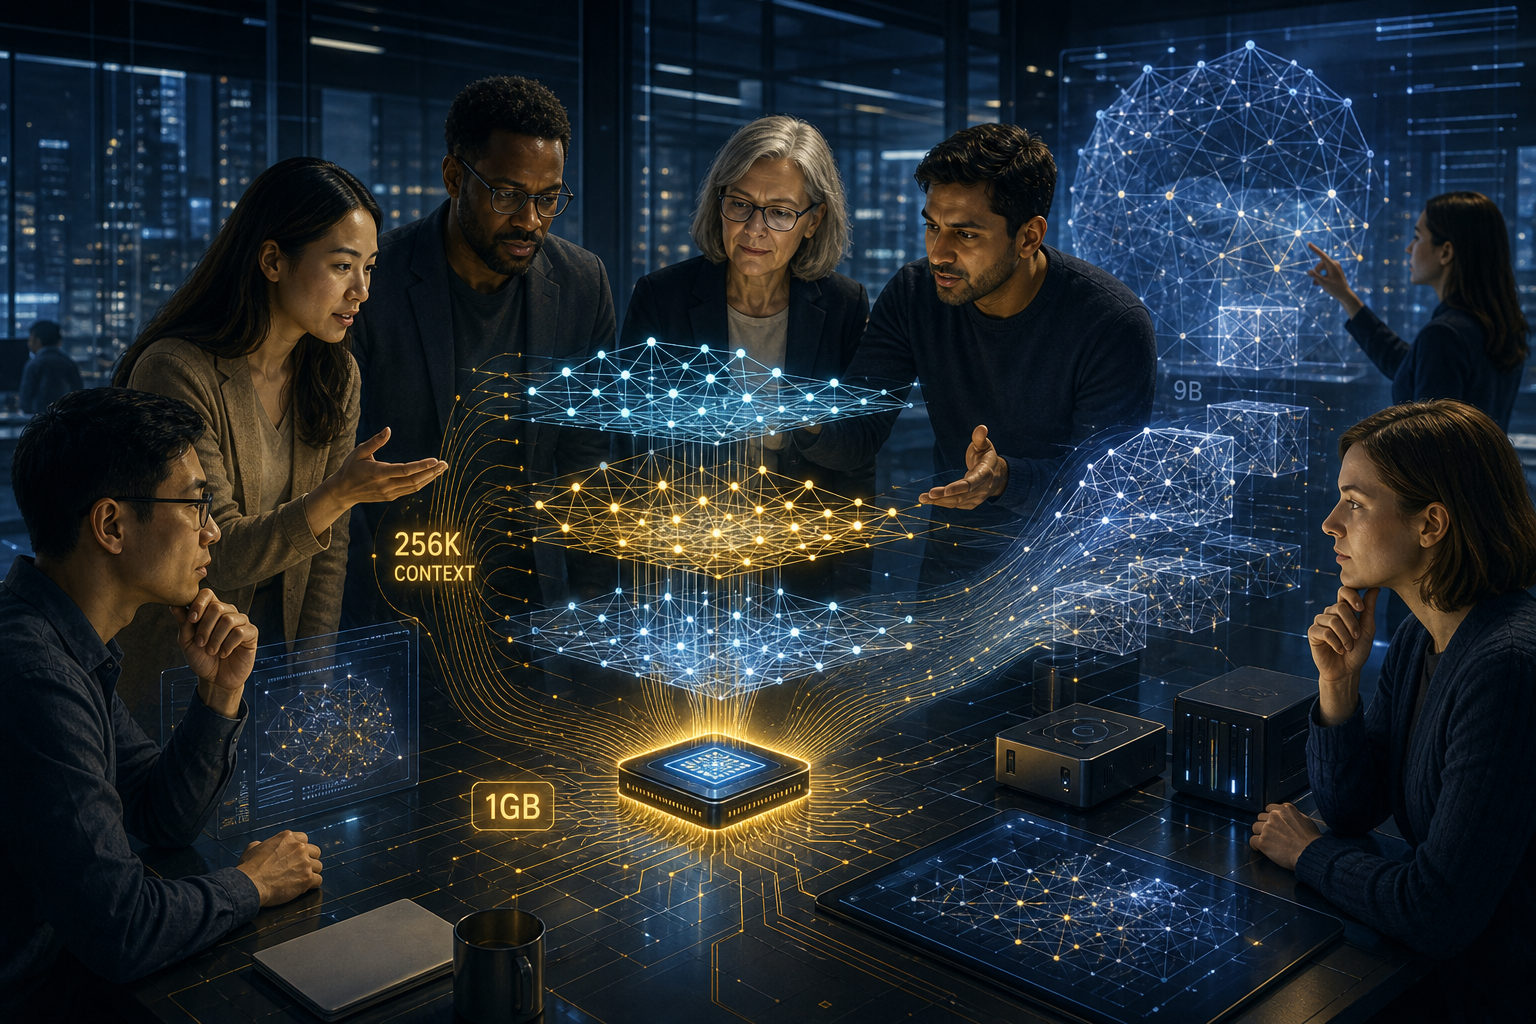
LFM3's core innovation lies in its unique "tri-hybrid" backbone architecture, which integrates three distinct computational mechanisms across 24 layers:
1. Gated Short Convolutions (13 Layers)
Using a kernel size of 7, these convolutions process local patterns with O(1) state memory. This design dramatically reduces memory overhead during inference, enabling the model to run efficiently on resource-constrained hardware.
2. Sliding-Window Attention (5 Layers)
A 256-token sliding window bridges the gap between local convolutions and long-range attention, ensuring the model captures medium-range semantic relationships.
3. Global Attention (6 Layers)
Six global attention layers handle contexts up to 256K tokens, enabling the model to understand and reason over complex long documents.
This tri-hybrid design reduces the KV cache footprint to approximately 27% of a standard transformer of similar depth — the key reason LFM3 can run within just 1GB of memory.
Performance Benchmarks: Remarkable Small-Beats-Large Results
Agentic Task Benchmarks
| Benchmark | LFM3-1.7B | Qwen3.5-9B | Advantage |
|---|---|---|---|
| AutomationBench | 41.29 | 15.10 | 2.7× |
| WebArena-Verified | 38.42 | 28.94 | 1.3× |
| IFEval (Instruction Following) | 96.66 | — | — |
LFM3-1.7B scores 2.7× higher than Qwen3.5-9B on AutomationBench and leads by 33% on WebArena-Verified. This means LFM3 can handle more complex automated workflows and web agent tasks with significantly less compute.
Hardware Compatibility
LFM3 has been validated on:
- Samsung Galaxy S26 Ultra (mobile)
- Raspberry Pi 5 (embedded devices)
- NPU-enabled laptops (edge computing)
For Asia-Pacific enterprises, this means deploying high-performance AI agents locally without cloud connectivity.
The LFM3 Family: Six Models for Every Scenario
The LFM3 series includes six models, all branched from the LFM3-1.7B-Base backbone:
Text and Multimodal Models
- LFM3-1.7B: Flagship text model, 256K context, 1GB memory footprint
- LFM3-VL-2B: Supports video input and visual chain-of-thought reasoning
- LFM3-Audio-2B: 50ms low-latency streaming audio encoder for speech recognition and synthesis in 18 languages
- LFM3-Omni-2B: Unified model for simultaneous text, vision, and audio processing
Decision Models
- d1-2B: Specialized decision model for structured outputs (classifications, scores) in a single forward pass
- d1-Omni-2B: Multimodal decision model optimized for high-speed triage tasks like support ticket routing
Deployment and Licensing: What It Means for APAC Enterprises
LFM3 is released under the LFM Open License v1.0, which allows free use for entities with under $10 million in annual revenue — particularly friendly for APAC SMEs and startups.
Supported Inference Frameworks
llama.cpp(GGUF format)vLLMSGLangMLX(Apple Silicon optimized)
APAC Deployment Advantages
For Asia-Pacific enterprises, LFM3's local deployment capability addresses several critical pain points:
- Data Sovereignty: Sensitive data never leaves the local environment, complying with regional data protection regulations
- Low Latency: Local inference eliminates network round-trip delays for real-time applications
- Cost Predictability: No per-token billing; large-scale deployment costs are predictable
- Offline Capability: Operates normally in environments with unstable connectivity
Technical Limitations: An Honest Assessment
Liquid AI acknowledges that LFM3 still trails larger models in:
- Agentic coding (SWE-bench): Complex code generation tasks
- General knowledge (GPQA Diamond): Q&A requiring broad knowledge bases
This means LFM3 is best suited as the "execution layer" at the edge, rather than the "planning layer" for deep reasoning. In hybrid architectures, LFM3 can handle high-frequency, low-complexity tasks locally while offloading complex reasoning to cloud models.
Industry Impact: A New Paradigm for Edge AI
LFM3's release marks an important inflection point: performance is no longer proportional to scale.
The conventional wisdom that bigger models mean better performance has been challenged. LFM3 demonstrates that through careful architectural design, small models can outperform large ones on specific tasks.
For the Asia-Pacific AI ecosystem, this breakthrough means:
- More enterprises can afford high-performance AI deployment
- Edge devices will become important nodes for AI inference
- Data privacy and localization requirements can be better met
Conclusion
Liquid AI LFM3 combines 1.7B parameters, 1GB memory footprint, and a 256K context window to outperform competitors five times its size on agentic tasks. This is not just a technical breakthrough — it's an important step toward AI democratization. For Asia-Pacific enterprises and developers, LFM3 provides a viable path to deploying high-performance AI agents on local devices, potentially accelerating AI adoption across the region.
Sources: Liquid AI Official Blog (October 29, 2026), TechTimes (October 30, 2026), Marktechpost (October 27, 2026)