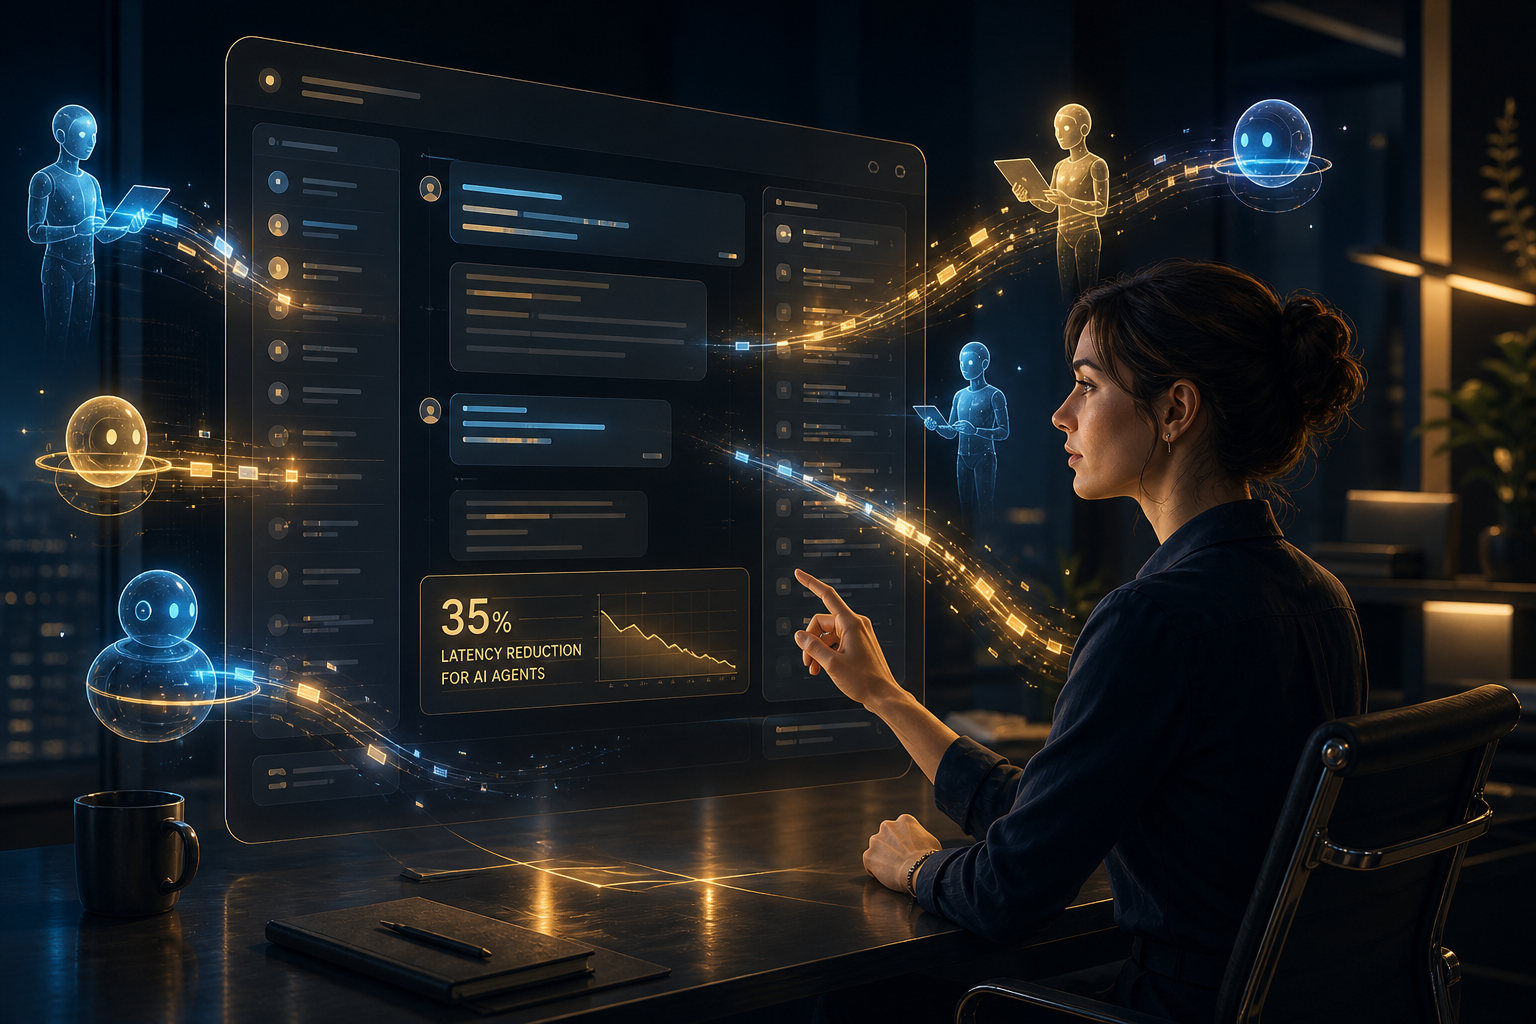
Anthropic Claude Message Threads Public Beta: 35% Latency Reduction for AI Agents
The Core Breakthrough: Delta Changes, Not Full History
On November 2, 2026, Anthropic officially launched the public beta of "Message Threads" for the Claude Messages API — a significant performance optimization targeting long-conversation AI agent scenarios. Traditional API architecture required every request to retransmit the complete conversation history, creating substantial overhead in network transmission, JSON parsing, and validation as conversations extended to hundreds of thousands of tokens.
The core innovation of Message Threads is straightforward: the first request sends the complete context, while subsequent requests send only new messages plus the ID of the previous response. Anthropic maintains conversation state in encrypted server RAM, reconstructing the full context before model inference — dramatically reducing client-side transmission overhead without changing model behavior.
Performance Data: What 35% Latency Reduction Means in Practice
According to Anthropic's official testing data:
| Request Scale | Traditional API TTFT | Message Threads TTFT | Reduction |
|---|---|---|---|
| 500K Tokens | Baseline | ~35% lower | Significant |
| 1M Tokens | Baseline | ~35% lower | Significant |
For AI agent scenarios requiring sustained long conversations — coding assistants, computer-use agents, customer service bots — a 35% reduction in Time to First Token (TTFT) represents a qualitative leap in user experience. For a coding agent processing 1 million tokens of context, each response wait time can be shortened by several seconds, with cumulative benefits that are extremely significant in high-frequency interaction scenarios.
Importantly, Message Threads does not change token billing — the model still reads the complete conversation, and total token usage and costs remain unchanged. The optimization is purely at the network transmission layer.
Technical Architecture Deep Dive
Workflow
- Initialization Request: Client sends complete conversation context; API returns response and Thread ID
- Subsequent Requests: Client sends only new messages + previous response ID
- Server Reconstruction: Anthropic servers retrieve Thread state from encrypted RAM and reconstruct full context
- Model Inference: Model receives complete context for inference, behavior identical to traditional API
Technical Limitations and Considerations
- Thread Lifetime: Thread state is stored in encrypted RAM and expires after 5 minutes of inactivity
- Expiration Handling: When a thread expires, the API returns a 404 error; clients must resend full history to reinitialize
- Compliance Restrictions: Not supported for zero data retention configurations or HIPAA-compliant setups
- Developer Responsibility: Developers must maintain local copies of complete conversation history to handle thread expiration
Platform Support
Message Threads is now live on:
- Native Claude Platform
- Amazon Web Services (AWS)
- Microsoft Azure AI Foundry
- Google Cloud Vertex AI
Claude Code users have the feature enabled by default with no additional configuration required.
Asia-Pacific Impact: Enterprise AI Agent Deployment Cost Optimization
For enterprise AI developers in the Asia-Pacific region, Message Threads brings not just performance improvements but real infrastructure cost optimization.
Japan: Japanese enterprises widely adopt Claude as the foundation for enterprise AI assistants. Long-conversation scenarios — legal document review, customer service — will directly benefit from reduced latency.
Singapore and Southeast Asia: Cross-border business scenarios where AI agents must maintain complex multi-turn conversation contexts will see significant reduction in API call network overhead, particularly important for cloud services deployed in the Asia-Pacific region.
Hong Kong and Taiwan: AI agent applications in fintech and legaltech typically involve large document contexts; the 35% latency reduction can directly improve end-user experience.
Comparison with Competitors
Anthropic's update represents a significant investment in AI agent infrastructure. By comparison:
- OpenAI simultaneously launched the Pando Git backend, focusing on agent-scale code infrastructure
- Google improved model capabilities with Gemini 4 Carbon, but with relatively less focus on API-layer agent optimization
- Anthropic chose to address the core pain point of long-conversation agents at the API infrastructure layer
This strategy reflects Anthropic's deep understanding of enterprise AI agent deployment — in real production environments, latency and reliability often impact user experience more directly than model capability.
Developer Best Practices
For developers planning to adopt Message Threads:
- Evaluate applicable scenarios: Message Threads is best suited for long-running agent tasks with conversations exceeding 100K tokens
- Implement expiration handling: Must maintain complete conversation history locally and implement automatic reinitialization logic after thread expiration
- Monitor TTFT metrics: Recommended to monitor Time to First Token in production to quantify actual performance gains
- Note compliance requirements: HIPAA-compliant scenarios are not yet supported; traditional API mode must be used
Outlook: The Evolution of AI Agent Infrastructure
The launch of Message Threads marks a new phase in AI agent infrastructure — shifting from "model capability competition" to "engineering efficiency optimization." As AI agent deployment scales continue to expand in enterprise environments, API-layer performance optimization will become an important dimension of differentiated competition.
Anthropic stated that Message Threads is currently in public beta and will continue to be optimized based on developer feedback, with plans to expand support for more compliance scenarios.
Frequently Asked Questions
Q: Will Message Threads increase API costs? A: No. Message Threads does not change token billing. The model still reads the complete conversation, and total costs are the same as the traditional API. The optimization is purely at the network transmission efficiency level.
Q: Will data be lost when a thread expires? A: Thread state is stored in encrypted RAM and expires after 5 minutes of inactivity, then cleared from memory. Developers must maintain local copies of complete conversation history; after expiration, resending the full history restores the session.
Q: Can AWS and Google Cloud users in Asia-Pacific use this? A: Yes. Message Threads is live on AWS, Microsoft Azure AI Foundry, and Google Cloud Vertex AI, directly accessible to enterprise users in the Asia-Pacific region.
Q: Do Claude Code users need to manually enable this? A: No. Claude Code users have Message Threads enabled by default with no additional configuration needed.
Q: Is Message Threads effective for short conversations? A: The benefit is limited. Message Threads primarily targets long-conversation scenarios of 500K to 1M tokens; for short conversations where transmission overhead is already small, the optimization benefit is minimal.